 Site
Kubernetes Cost Optimization: 12 Hidden Mistakes
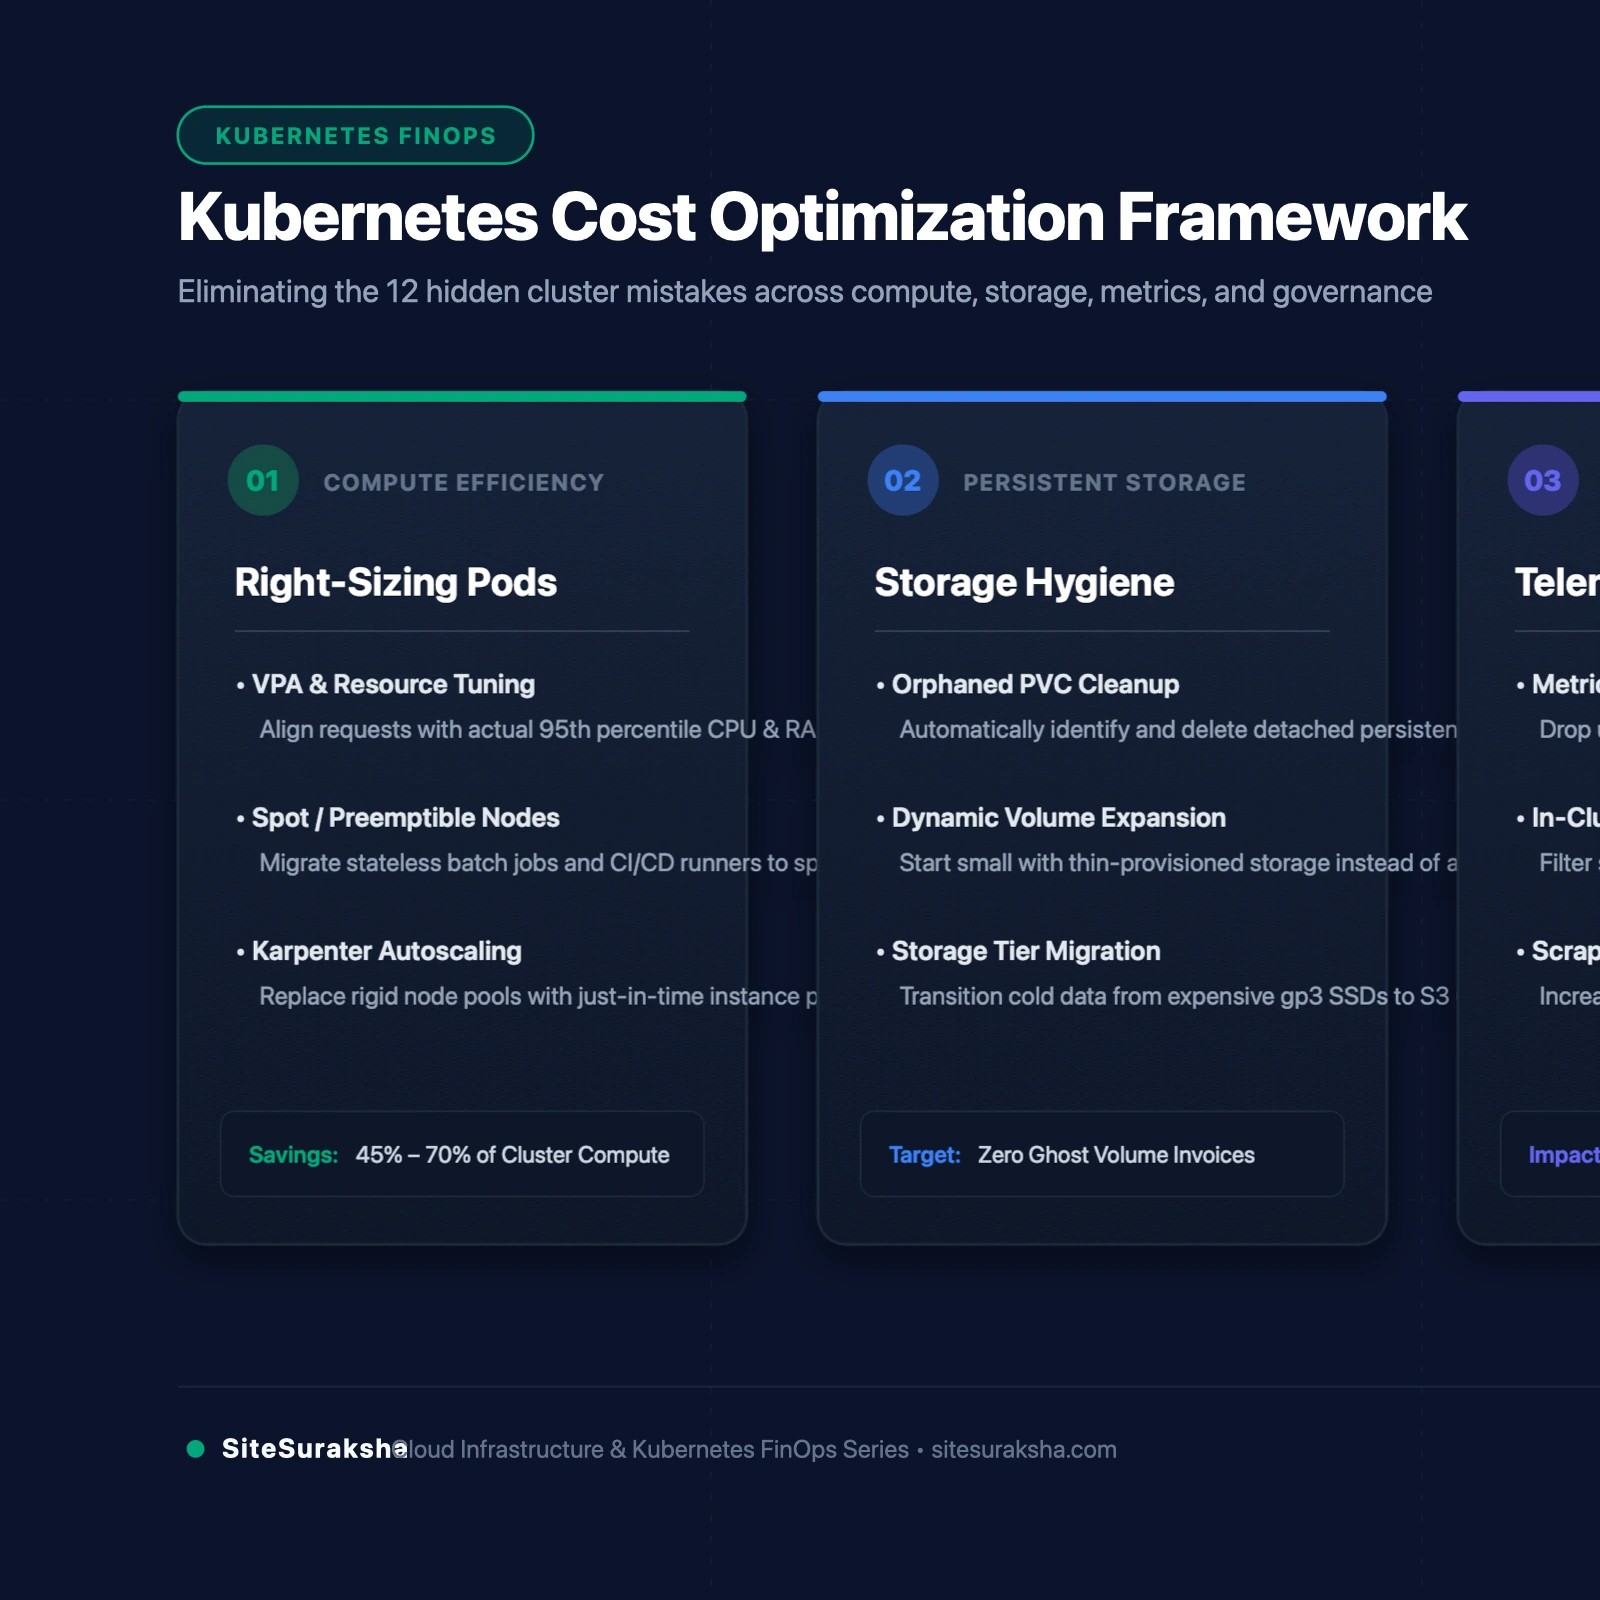
Kubernetes Cost Optimization: 12 Hidden Mistakes Quietly Increasing Your Cloud Bill
Chat with an engineer on WhatsApp within 15 minutes.
Kubernetes was designed to improve scalability, agility, and operational efficiency. Ironically, for many organizations, it becomes one of the fastest-growing sources of unexpected cloud spend.
Teams adopt Kubernetes to accelerate deployments and simplify infrastructure management across platforms like Amazon EKS, Azure Kubernetes Service (AKS), and Google Kubernetes Engine (GKE). But after a few months, many organizations notice something concerning: cloud costs begin increasing much faster than actual application usage.
The issue usually isn’t Kubernetes itself. The real problem lies in how clusters are configured, scaled, monitored, and governed over time. Across many enterprises, Kubernetes environments gradually develop silent cost leaks that remain unnoticed until monthly cloud bills begin attracting attention from finance and leadership teams.
Most Kubernetes cost inefficiencies do not come from a single major mistake. Instead, they emerge from multiple small inefficiencies accumulating silently across compute, storage, autoscaling, observability, and workload management practices.
In this blog, we’ll explore 12 common Kubernetes cost optimization mistakes that quietly increase cloud bills, and how organizations can proactively address them.
The 12 Hidden Mistakes
1. Overprovisioned CPU and Memory Requests
One of the biggest Kubernetes cost optimization challenges is resource overprovisioning. To avoid performance issues, engineering teams often allocate significantly more CPU and memory than applications actually consume.
Example: actual application usage of 200m CPU against a configured request of 2 vCPU. While this may appear harmless initially, the impact becomes substantial when repeated across hundreds of workloads.
Because Kubernetes schedules workloads based on requested resources rather than actual utilization, oversized requests directly lead to larger node pools, lower cluster utilization, and increased infrastructure costs. In large Kubernetes environments, even a 15–20% overprovisioning gap can translate into significant monthly cloud waste.
Optimization approach, continuously monitor:
- CPU utilization
- Memory consumption
- Peak traffic behavior
- Historical workload patterns
Right-sizing workloads based on actual usage is one of the most effective Kubernetes cost optimization strategies.
2. Idle Worker Nodes Running 24/7
Many Kubernetes clusters continue running full node capacity even during nights, weekends, and low-traffic periods. This issue is especially common in development environments, QA clusters, sandbox workloads, and internal testing environments. Idle infrastructure silently increases Kubernetes cloud costs over time.
Optimization approach, implement:
- Cluster Autoscaler
- Scheduled scaling policies
- Automated node shutdown
- Environment scheduling for non-production workloads
Reducing idle compute usage often delivers immediate cost savings.
3. Zombie Namespaces and Forgotten Resources
As Kubernetes environments evolve, unused resources begin accumulating silently. Common examples include old namespaces, forgotten deployments, unused services, abandoned Helm releases, and expired test environments. Without governance and ownership tracking, these resources continue consuming infrastructure indefinitely.
Optimization approach, establish:
- Namespace ownership tagging
- Resource expiration policies
- Periodic cleanup reviews
- Automated stale-resource detection
Strong governance is critical for long-term Kubernetes cost management.
4. Running Workloads on Oversized Instance Types
Many organizations choose larger VM instances assuming “bigger is safer.” However, oversized worker nodes frequently create poor pod packing, unused compute capacity, inefficient scaling behavior, and infrastructure waste. Larger instances do not always improve efficiency.
Optimization approach, adopt:
- Balanced node pools
- Mixed instance groups
- Workload-aware scheduling
- Instance diversification strategies
Efficient workload distribution significantly improves infrastructure utilization.
5. Ignoring Spot and Preemptible Instances
Many Kubernetes workloads can safely run on lower-cost compute models such as AWS Spot Instances, Azure Spot Virtual Machines, and GCP Preemptible Instances. Yet many organizations continue running all workloads on expensive on-demand infrastructure.
Suitable workloads include:
- CI/CD runners
- Batch jobs
- Analytics processing
- Stateless services
- Asynchronous workloads
When implemented correctly, Spot and Preemptible workloads can reduce Kubernetes compute costs substantially without affecting production stability.
6. Excessive Logging and Monitoring Costs
Observability costs are one of the most overlooked contributors to Kubernetes cloud spending. As environments scale, organizations generate enormous volumes of logs, metrics, traces, and telemetry data. In some environments, observability platforms themselves become major cost centers.
Common issues: excessive debug logging, long retention periods, duplicate telemetry pipelines, high-frequency metric collection, and unfiltered log ingestion.
Optimization approach, regularly review:
- Log retention policies
- Metrics collection frequency
- Trace sampling strategies
- Logging verbosity levels
Observability should improve visibility, not create uncontrolled cost growth.
7. Missing Resource Limits
Without proper CPU and memory limits, workloads can consume excessive resources and trigger unnecessary cluster expansion. This often results in noisy neighbor issues, unstable cluster behavior, reduced efficiency, and higher infrastructure costs.
Optimization approach, implement:
- CPU limits
- Memory limits
- Namespace quotas
- Governance guardrails
- Resource validation policies
Controlled resource usage improves both reliability and cost efficiency.
8. Persistent Storage Waste
Storage inefficiencies often remain hidden because they grow gradually over time. Common examples include unattached persistent volumes, old snapshots, unused PVCs, and long-retained backups. Because storage costs accumulate silently, they frequently go unnoticed until environments scale significantly.
Optimization approach, regularly audit:
- Persistent Volume Claims (PVCs)
- Snapshot retention
- Backup policies
- Orphaned storage resources
Automated storage lifecycle management helps reduce long-term waste.
9. Poor Autoscaling Configuration
Autoscaling helps, but poorly configured autoscaling can actually increase Kubernetes cloud costs. Common problems include aggressive scaling thresholds, slow scale-down behavior, excessively high minimum node counts, and inefficient HPA configuration.
Optimization approach, continuously review:
- HPA thresholds
- Cluster Autoscaler settings
- Node scale-down timing
- Minimum and maximum node counts
Autoscaling should optimize efficiency, not accelerate unnecessary infrastructure growth.
10. Running Too Many Small Clusters
As organizations grow, cluster sprawl becomes increasingly common. However, too many Kubernetes clusters increase control plane costs, infrastructure duplication, operational overhead, and governance complexity.
Optimization approach, evaluate:
- Shared clusters
- Namespace isolation
- Multi-tenant governance
- Centralized observability
- Platform standardization
In many cases, fewer well-governed clusters operate far more efficiently than multiple isolated environments.
11. Lack of Team-Level Cost Visibility
Engineering teams often have limited visibility into the financial impact of their infrastructure decisions. Without proper cost allocation, overspending remains unnoticed, optimization accountability disappears, and inefficient workloads continue growing.
Optimization approach, implement:
- Namespace-level cost allocation
- Labels and annotations
- Team-level dashboards
- Chargeback / showback reporting
- FinOps visibility for engineering teams
Cost transparency drives better engineering decisions.
12. Treating Kubernetes Cost Optimization as a One-Time Project
One of the biggest misconceptions is viewing Kubernetes optimization as a one-time initiative. Kubernetes environments constantly evolve due to new deployments, traffic pattern changes, scaling events, and infrastructure updates. Without continuous governance, inefficiencies quickly return.
Optimization approach. Kubernetes cost optimization should become an ongoing operational discipline involving:
- Continuous monitoring
- Governance automation
- Engineering accountability
- Periodic optimization reviews
- FinOps integration into engineering workflows
Long-term optimization requires continuous operational maturity.
Key Takeaways
- Most Kubernetes cloud cost waste comes from multiple small inefficiencies accumulating over time
- Overprovisioning and idle infrastructure remain the largest hidden contributors
- Observability and storage costs often grow silently without governance
- Continuous optimization is more effective than reactive cost reduction exercises
- FinOps visibility should extend directly into engineering workflows
Final Thoughts
Kubernetes delivers exceptional scalability, flexibility, and deployment speed. However, without strong governance and operational discipline, it can also introduce hidden financial inefficiencies that silently grow over time.
Organizations that continuously monitor workload sizing, autoscaling behavior, idle infrastructure, storage growth, observability usage, and engineering governance are often able to reduce unnecessary Kubernetes spending significantly, without affecting application performance or developer velocity.
In modern cloud environments, proactive Kubernetes cost optimization is far more effective than reacting after cloud costs have already escalated.
How SiteSuraksha Helps
At SiteSuraksha, we help organizations improve cloud financial visibility, governance, and infrastructure efficiency across AWS, Azure, and GCP environments.
As Kubernetes adoption continues to grow, organizations increasingly require proactive cost governance, engineering accountability, and continuous optimization visibility across cloud-native infrastructure.
SiteSuraksha helps teams operationalize FinOps practices across Kubernetes environments before cloud costs escalate.
Save on Cloud and AI. Get a Demo.
A short call to understand what you run, then a demo built around it. Not a slide deck,
and nothing to install.
- 1
Tell us what you are running
Enough to make the demo yours rather than generic. We do not touch your account to show you this.
2 minutes
- 2
A short call to understand your setup
Which clouds you run, how you ship, and where the cost questions actually come from.
15 minutes, within 1 business day
- 3
We show you your cost footprint
Cloud and AI spend in one view: what you are running, what it costs, and where it is concentrated.
30-minute demo, built for your stack
- 4
You leave knowing what it would catch
We price a real pull request in front of you and route it for approval. That is the part no dashboard does. You see exactly which of your own changes would have been flagged.
Yours to keep, demo or not
Every demo includes the free SiteSuraksha Savings Report. Connect read-only and your savings opportunities come back within days, ranked by value, with a walkthrough call included. Read-only, always: we never modify your infrastructure.
Is Your Website Fast & Secure?
Run an instant scan for security vulnerabilities, bloated plugins, and TTFB latency.
Need Help Securing or Speeding Up Your Site?
Get 24/7 proactive security WAF, daily cloud backups, and sub-second speed optimization from ₹3,470/mo.